Consumption-based pricing and agentic workflows are multiplying token costs across the enterprise - and most of what gets sent to the model is never used.
60%
of enterprise CIOs are actively throttling or governing AI usage as token costs climb.
8 - 20
LLM calls per request in agentic workflows, each one multiplying the same token assumptions.
Key Challenges in Enterprise AI Usage
AI teams face mounting inefficiencies that impact cost, speed, security and productivity.
Tool Metadata Overload
Every available tool and its schema gets sent along, whether the request needs it or not.
Repeated Context Transfer
The same code and documents get re-sent turn after turn instead of reused.
Higher Response Latency
Bloated context takes longer to process, slowing down every response.
API Limits & Productivity Loss
Oversized requests burn through rate limits faster, stalling development work.
Low Signal, High Noise
The context that actually matters gets buried in everything that doesn’t.
Security & Compliance Risk
Proprietary code and documents travel to the cloud more often than they need to.
The Root Cause isn't the Model.
It's the Context Overload.
A Local Intelligence Layer
What eSL Vortex Does
eSL Vortex is a local intelligence layer that filters your codebase and documents, sending only what the AI actually needs, nothing more.
Find Only relevant Code & Documents
Semantic search across your entire codebase and document repository.
Remove Noise
Strips out everything that AI doesn’t need.
Instant Filtering
Zero latency – runs entirely on local CPU.
Runs Locally
Secured. No cloud infrastructure required.
eSL Vortex turns expensive, unfocused AI usage into a prudent engineering assistant - by delivering only the context that matters.
eSL Vortex Core Capabilities
Enterprise-Grade Intelligence, Under the Hood.
Enterprise-grade intelligence that optimises AI context to reduce costs, accelerate responses and improve accuracy.
Intelligent Code & Document Retrieval
Locates the exact code and documents your AI needs, out of your entire knowledge base.
Smart Tool & Metadata Selection
Chooses only the tools and metadata that a request actually needs.
Context Filtering & Compression
Cuts unnecessary content down to precise, high-value context.
Privacy & IP Protection
Keeps proprietary code and documents on-premises, by design.
Proprietary Hybrid Scoring
Ranks context by true relevance before it ever reaches the model.
Token & Cost Visibility
Clear, ongoing visibility into what every request actually costs.
Real-Time Adaptation
Adjusts as your codebase, documents, tools, and usage evolve.
Enterprise Ready
Built to deploy across large engineering organizations from day one.
eSL Vortex Value
Measurable Impact, Not Just Optimization
Reduce AI Spend
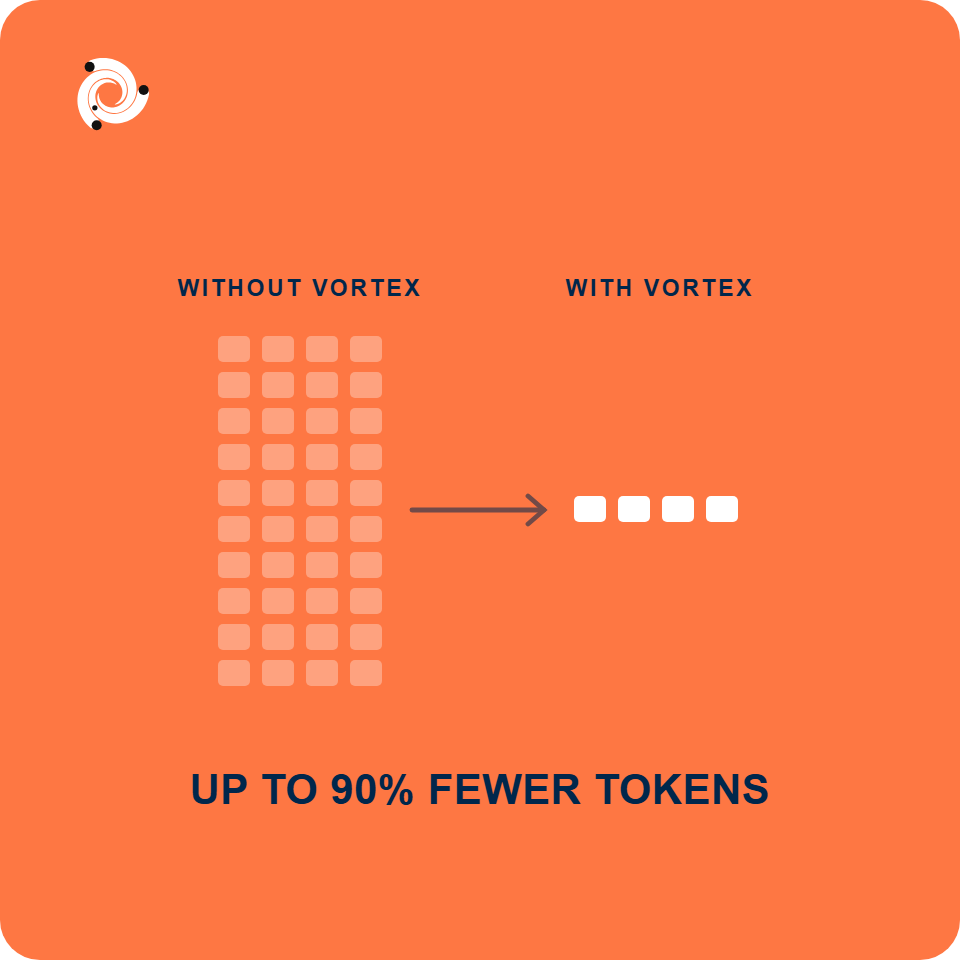
Slash token usage by sending only relevant context - not entire codebases and document sets.
90% Lower Token Usage
Accelerate Engineering
Smaller, smarter prompts mean lower latency and higher developer productivity.
2-5x Faster Response
Protect Enterprise Code & Documents
Code and documents stay on-premises. Only approved snippets ever leave your machine..
100% Data Residency Control
Improve AI Quality
Relevant context reduces hallucinations and delivers accurate, actionable answers.
Higher Answer Accuracy
Learning Loop
Continuously learns from usage to get smarter and better with every interaction.
Improving Smarter With Every Use
Ready to Reduce Your AI Spend?
See exactly how much noise your current AI workflows are paying for and what eSL Vortex recovers.